✦ THE RECODE HIVE BLOG

Engineering uptime

blog by recode community.

github.com/recodehive (opens in a new tab)

  • Aditya Singh Rathore
  • Sanjay Viswanathan
  • Sowmiya Venkatesan

3 authors have written 22 posts

Become one β†’ (opens in a new tab)

TOPIC SPOTLIGHT

Big data at scale

All Big Data posts β†’
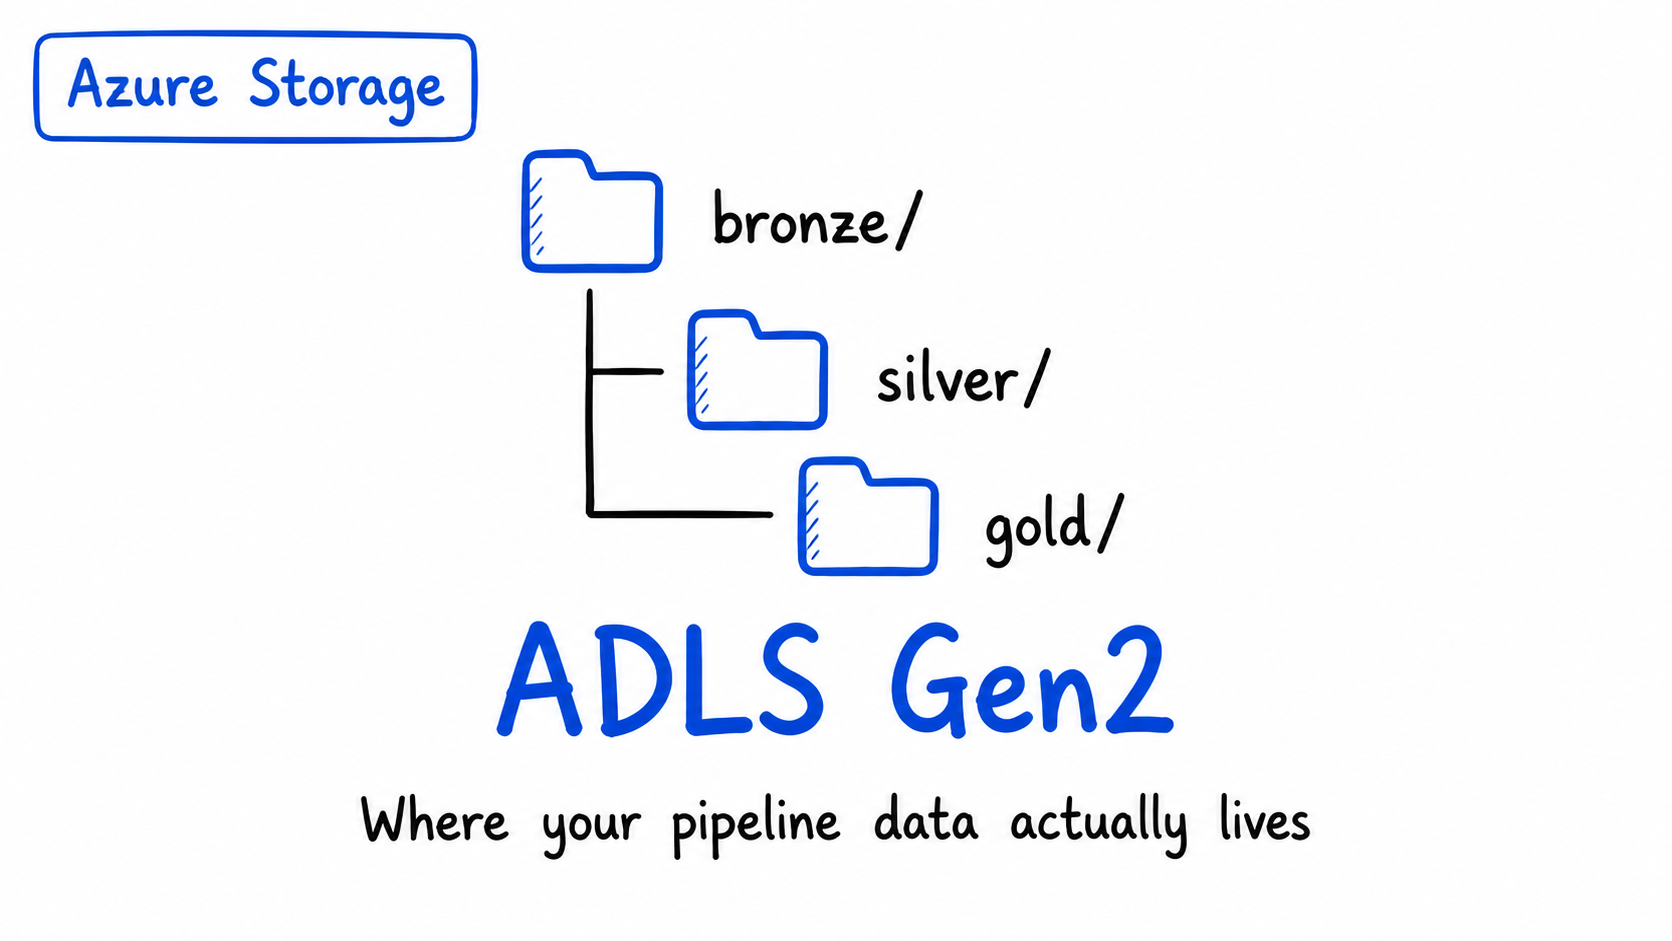
Azure Storage & ADLS Gen2: Where Does Your Data Actually Live?

AZURE

Azure Storage & ADLS Gen2: Where Does Your Data Actually Live?

Every Azure data pipeline needs a place to store data. But Azure gives you four different storage types and choosing the wrong one is easier than you think. This guide explains all four, shows how they work together in a real pipeline, and goes deep on ADLS Gen2, the storage layer that powers modern Azure data engineering.

  • Azure Storage
  • Blob Storage
  • ADLS Gen2

AZURE

Azure Synapse Analytics: When to Use It (And When to Choose Fabric Instead)

Azure Synapse Analytics is one of the most powerful tools in the Azure data stack. But in 2026, with Microsoft Fabric growing fast, the question isn't just "what is Synapse?" β€” it's "when should you still use it, and when should you move to Fabric?" Here's the honest answer.

  • Azure Synapse Analytics
  • Data Engineering
  • SQL Pools

EXPLORE ARTICLES

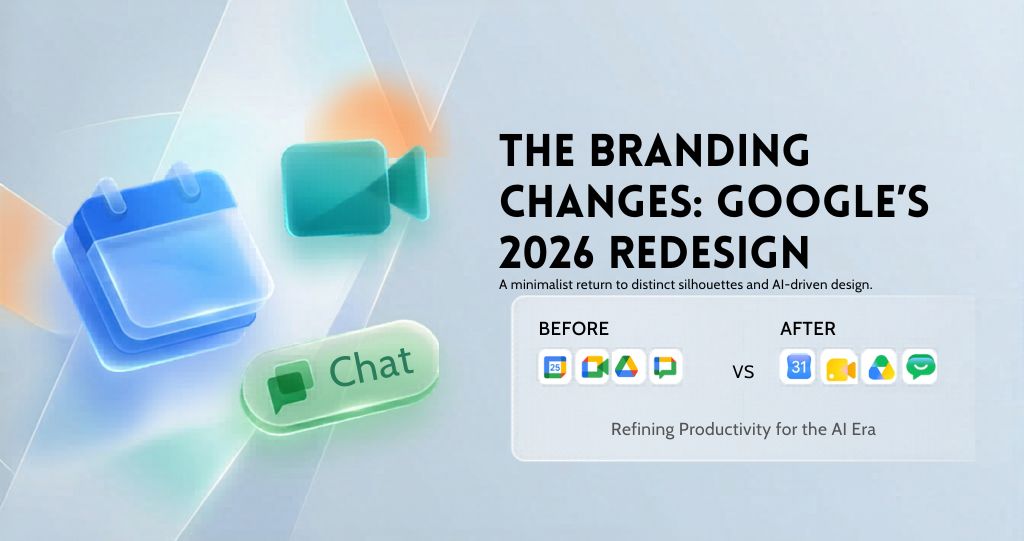
New Google Workspace Icons (2026): What Changed

DESIGN

New Google Workspace Icons (2026): What Changed

Google redesigned its Workspace icons in 2026, dropping the four-color rule from 2020. Here's what changed, why now, and whether it fixes the confusion.

  • Google Workspace
  • UI Design
  • UX
Why Data Engineers Make Better Business Analysts Than MBAs Do

CAREER

Why Data Engineers Make Better Business Analysts Than MBAs Do

MBAs learn to analyze businesses. Data engineers live inside the data those businesses actually run on. Here's why that difference matters more than any credential β€” and what both sides should learn from each other.

  • Data Engineering
  • Career
  • Business Analysis
Medallion Architecture: How to Stop Your Data Pipeline from Becoming a Nightmare

ARCHITECTURE

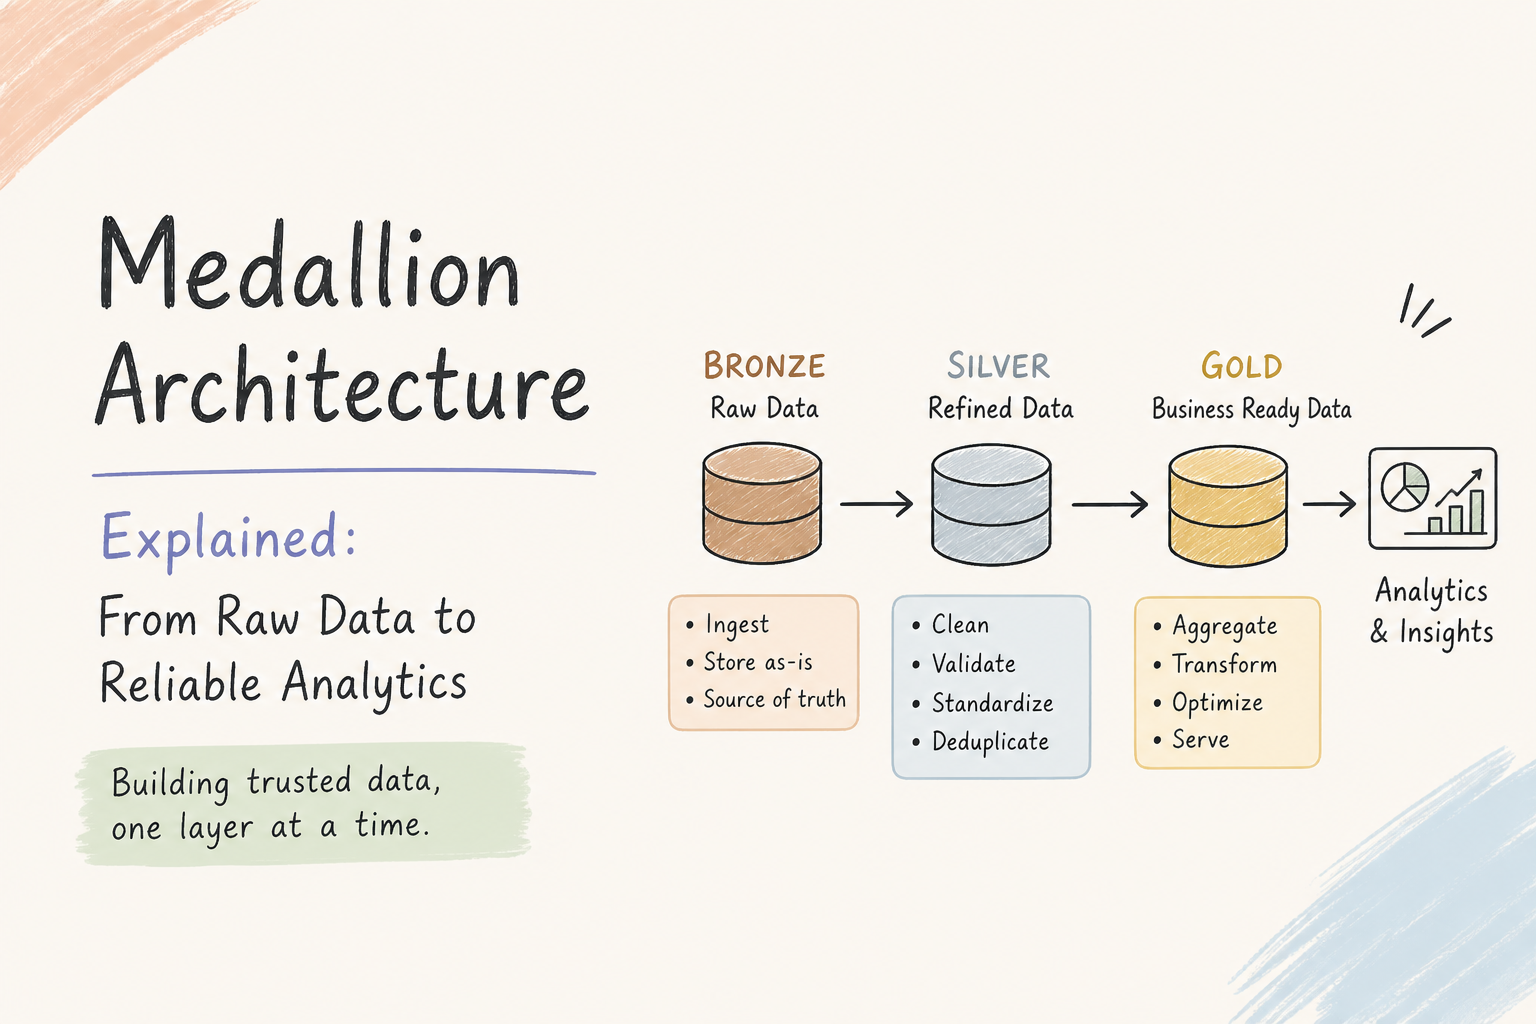
Medallion Architecture: How to Stop Your Data Pipeline from Becoming a Nightmare

Most data pipelines don't fail because of bad technology. They fail because raw data flows directly into reports with no checkpoints, no validation, and no clear ownership. Medallion Architecture fixes exactly this β€” here's how it works, why it matters, and how to implement it in practice.

  • Medallion Architecture
  • Data Engineering
  • Bronze Silver Gold
Azure Data Factory Pipeline: Build Your First ETL in 10 Minutes

TUTORIAL

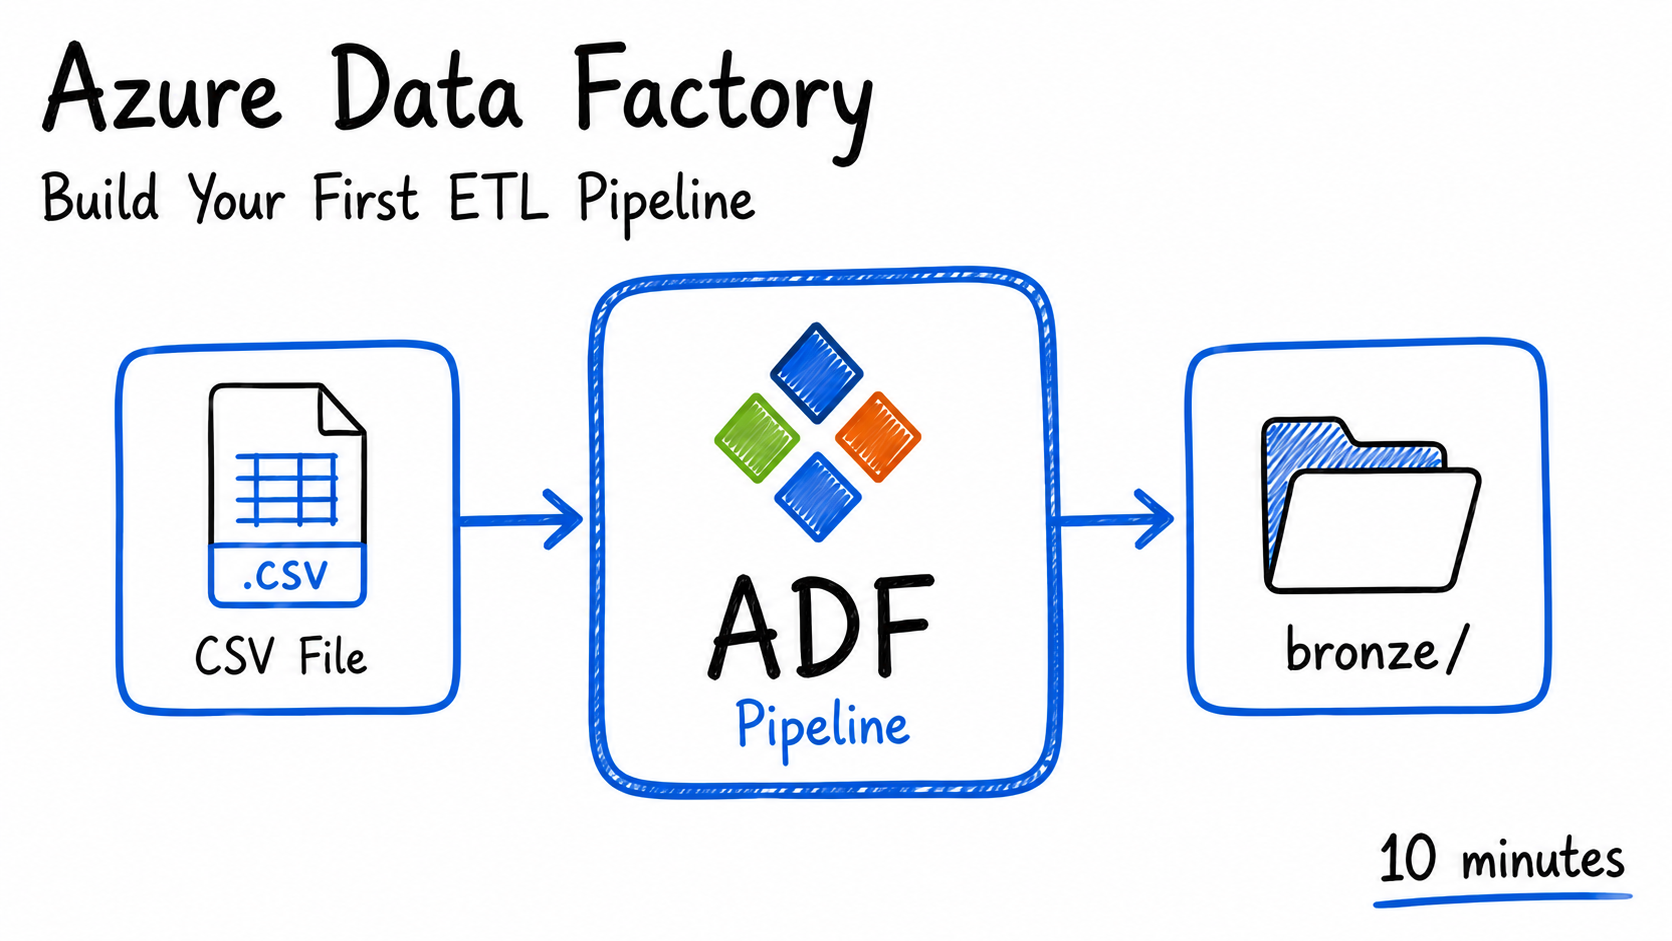
Azure Data Factory Pipeline: Build Your First ETL in 10 Minutes

Azure Data Factory is Microsoft's cloud-native ETL service β€” a visual, no-code platform for moving and transforming data at scale. This step-by-step guide walks you through building your first real pipeline in under 10 minutes, explaining every concept along the way.

  • Azure Data Factory
  • ADF
  • ETL
Azure Storage & ADLS Gen2: Where Does Your Data Actually Live?

AZURE

Azure Storage & ADLS Gen2: Where Does Your Data Actually Live?

Every Azure data pipeline needs a place to store data. But Azure gives you four different storage types and choosing the wrong one is easier than you think. This guide explains all four, shows how they work together in a real pipeline, and goes deep on ADLS Gen2, the storage layer that powers modern Azure data engineering.

  • Azure Storage
  • Blob Storage
  • ADLS Gen2
Azure Synapse Analytics: When to Use It (And When to Choose Fabric Instead)

AZURE

Azure Synapse Analytics: When to Use It (And When to Choose Fabric Instead)

Azure Synapse Analytics is one of the most powerful tools in the Azure data stack. But in 2026, with Microsoft Fabric growing fast, the question isn't just "what is Synapse?" β€” it's "when should you still use it, and when should you move to Fabric?" Here's the honest answer.

  • Azure Synapse Analytics
  • Data Engineering
  • SQL Pools
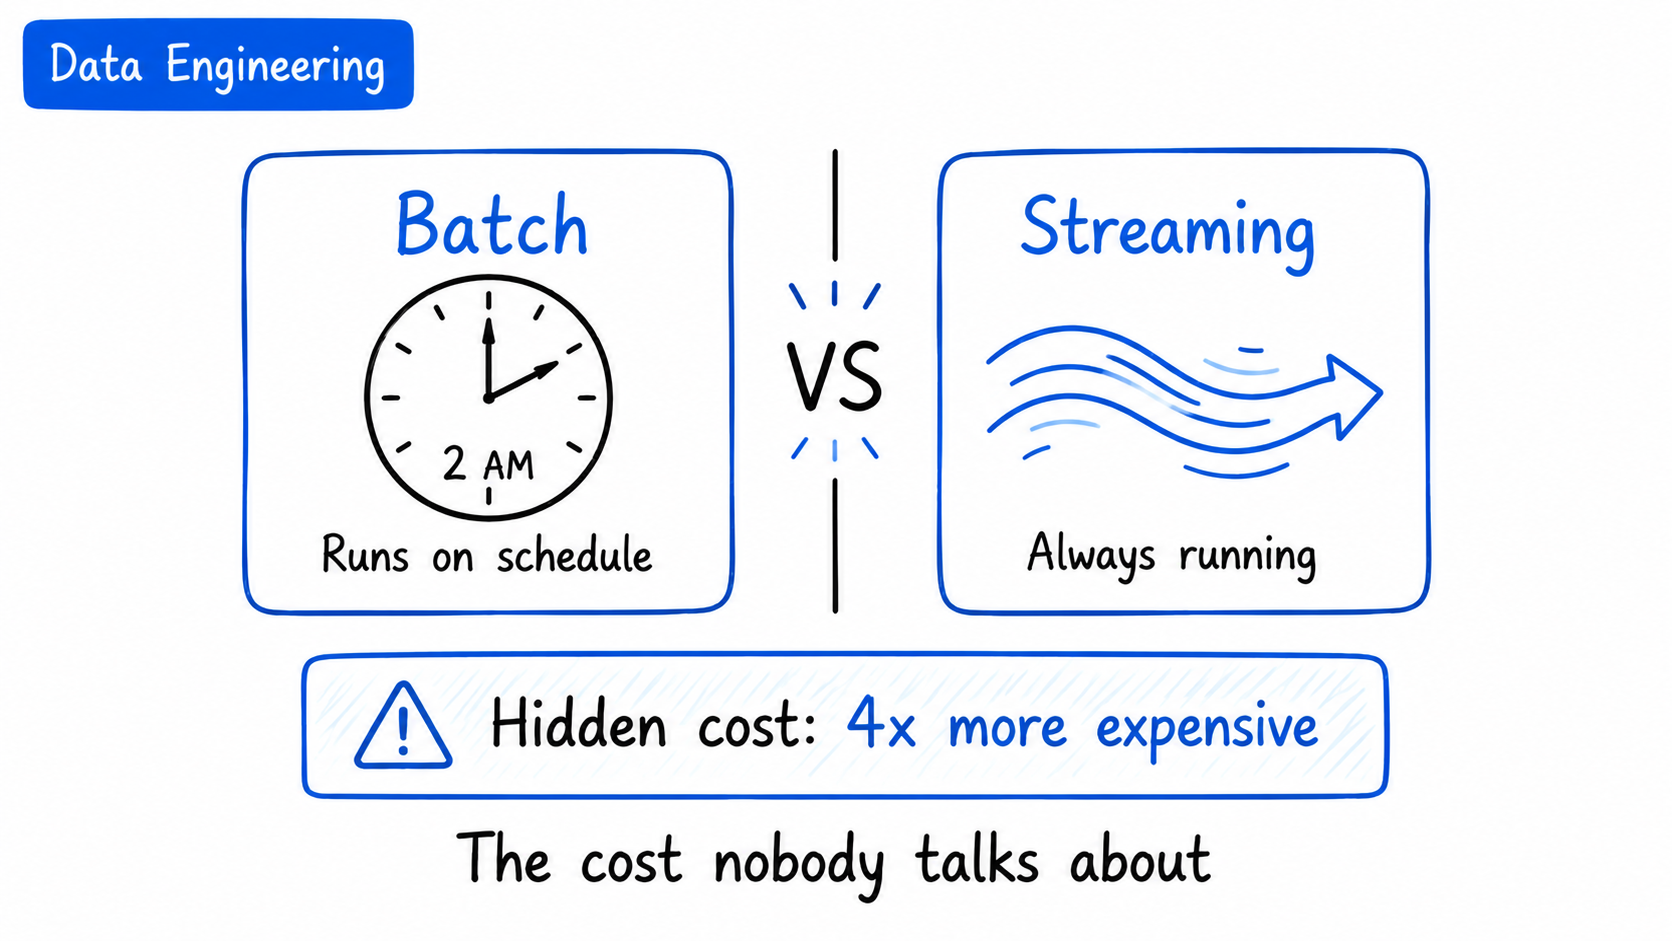
Why We Rolled Back Our Kafka Pipeline to Batch After 6 Months

STREAMING

Why We Rolled Back Our Kafka Pipeline to Batch After 6 Months

Everyone talks about the benefits of streaming pipelines β€” real-time insights, millisecond latency, live dashboards. Nobody talks about what it actually costs you. I rebuilt a working batch pipeline as a streaming system. Here's what I learned the hard way.

  • Batch Processing
  • Stream Processing
  • Data Engineering
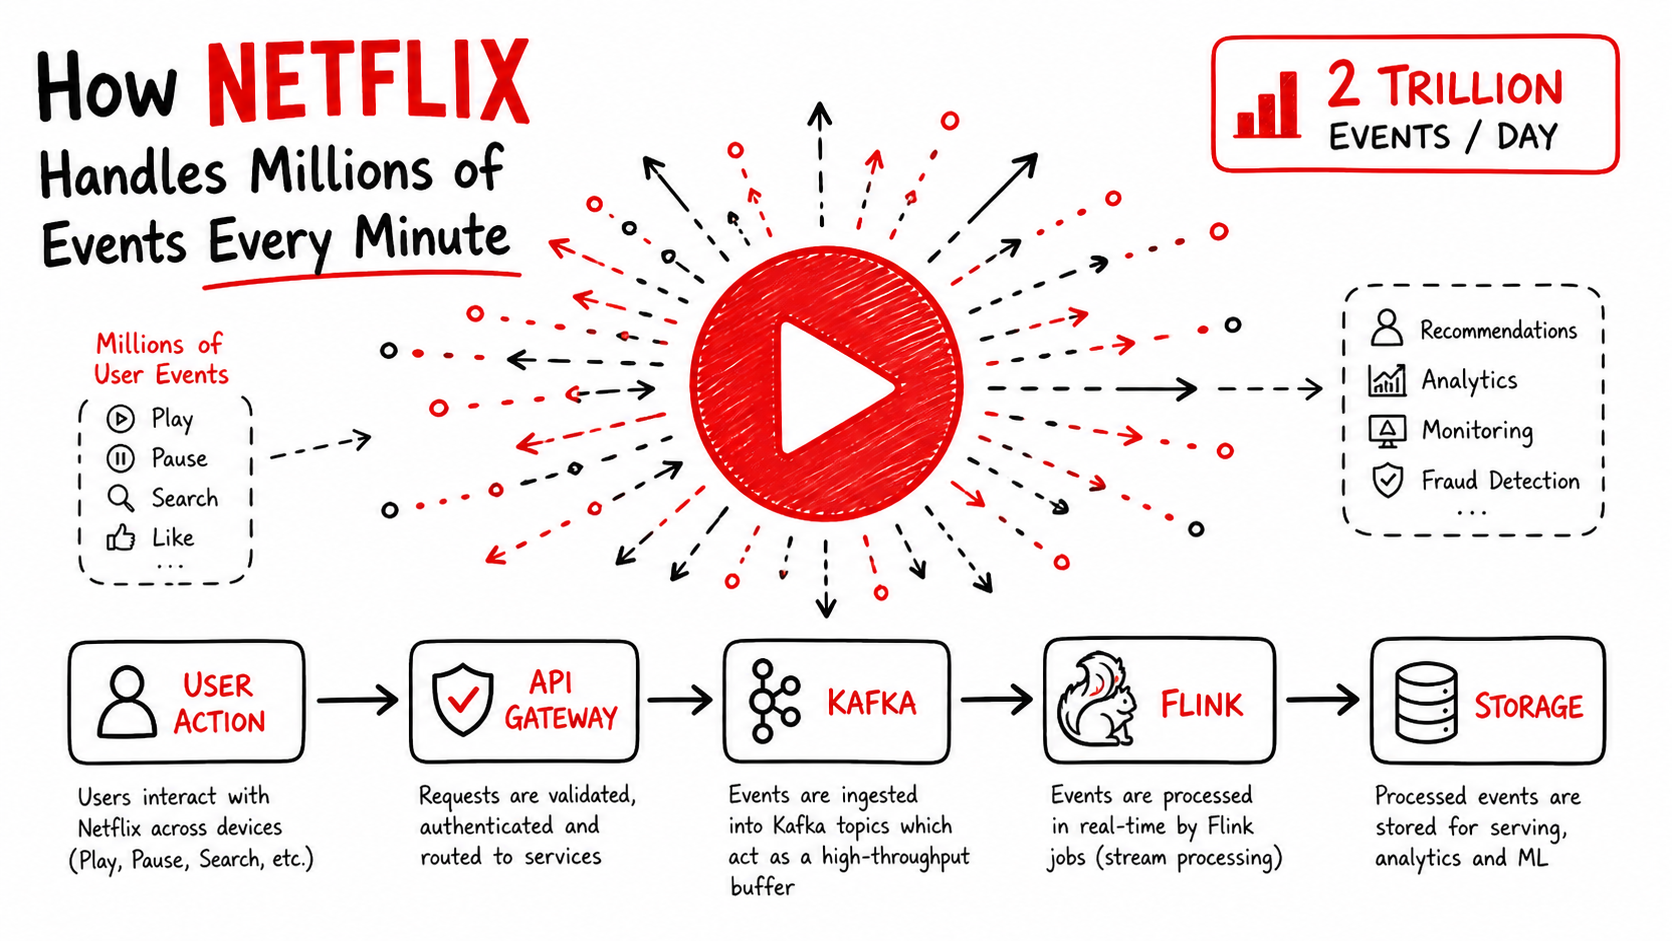
How Netflix Handles 2 Trillion Events Every Day

CASE STUDY

How Netflix Handles 2 Trillion Events Every Day

Every click, pause, search, and scroll on Netflix generates an event. With 300 million subscribers across 190 countries, Netflix processes 2 trillion events every single day through a pipeline called Keystone. Here's a deep dive into how Kafka, Flink, Cassandra, and Iceberg make it all work in real time.

  • Netflix
  • Data Engineering
  • Kafka
How SSO Works - Case Study

SECURITY

How SSO Works - Case Study

SSO lets you log into dozens of apps with a single set of credentials. But how does it actually work under the hood? This beginner-friendly guide walks through the full flow β€” from clicking "Sign in with Google" to getting access β€” step by step.

  • SSO
  • Single Sign On
  • Authentication
  1. SEO metadata refreshed on every blog post

    Titles, descriptions and social previews improved across the blog.

    #2296 @Adez017

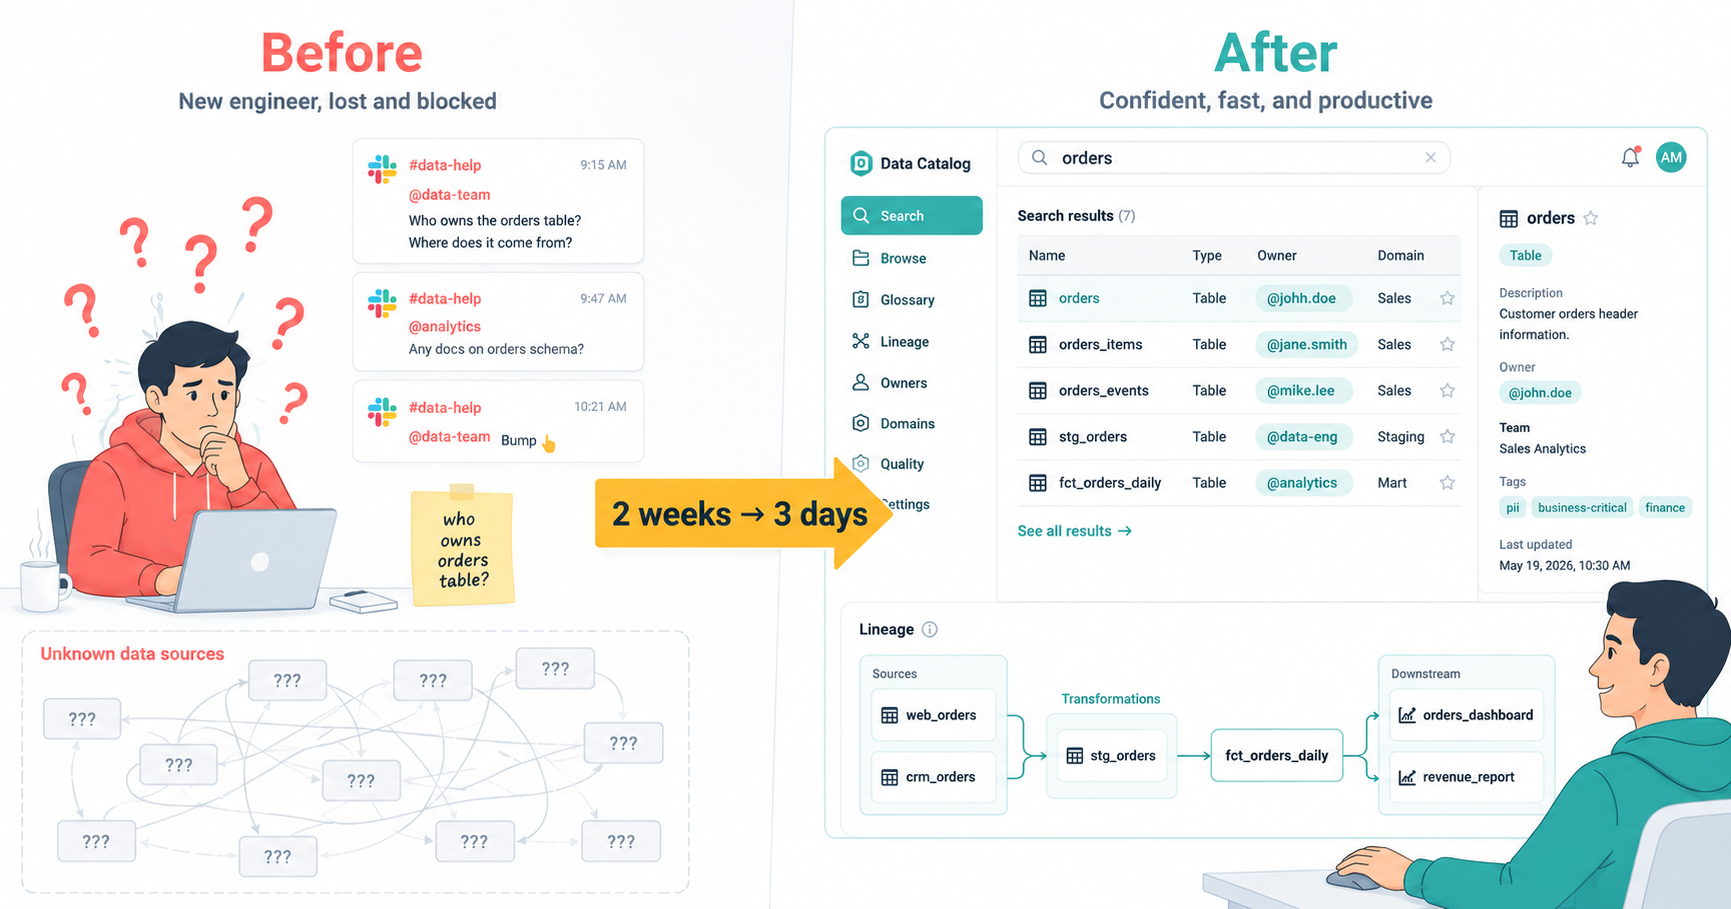
  2. How We Used Purview Data Catalog to Reduce Onboarding Time

    Post content updated after publishing.

    #2201 @Adez017

  3. Google Changed Workspace Icon after 6 years

    Duplicate line removed and text readability fixed.

    #1821, #1841 @hrx01-dev

  4. Azure Data Pipeline Cost Optimization: How We Cut a $4,200 Bill by 73%

    Post refactored and restructured.

    #1556 @Adez017

✦ WRITE FOR THE HIVE

Write technical blogs on recode hive and get featured.

Share what you built or learned. The strongest posts get the Featured spot on this page.